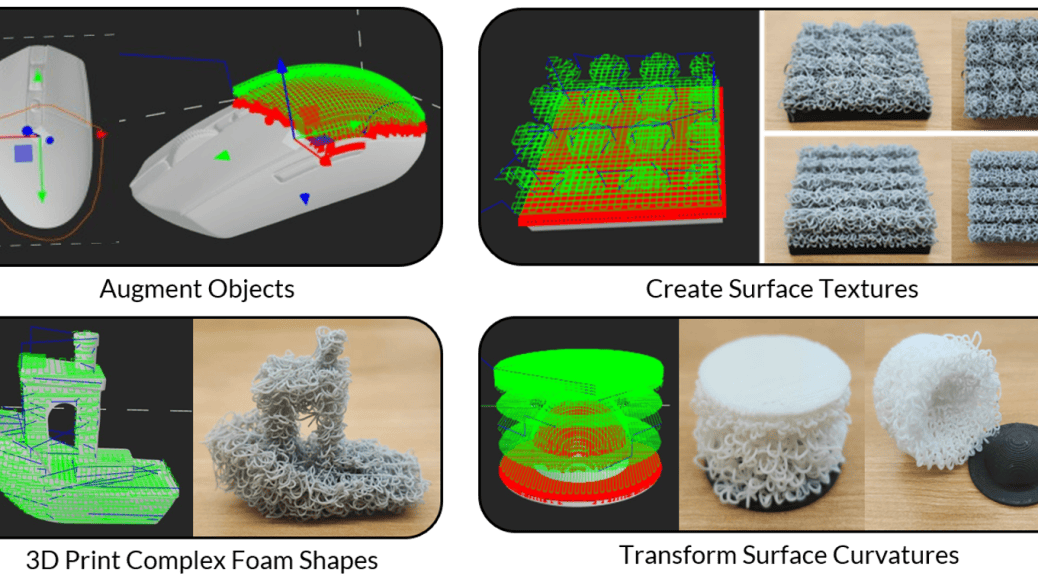
Combining soft-structure fabrication, direct-to-object augmentation, and embedded interactivity remains challenging, typically requiring specialized hardware, precise 3D scanning, or complex post-processing. AugPrint demonstrates how viscous thread printing (VTP) can bridge all three domains using an unmodified consumer-grade 3D printer. VTP leverages liquid rope coiling to deposit material from a high clearance, thereby inherently mitigating print head collisions on curved surfaces. The extruded filament remains viscous enough to passively conform to underlying geometries without requiring precise mesh alignment. We present a design tool that enables users to create gradient-density foam augmentations on curved surfaces with non-planar toolpath generation, stiffness control, and surface texturing. We also establish the viability of embedded pressure sensing using commercially available conductive TPU printed with VTP. We demonstrate these capabilities through end-to-end applications, including a pressure-mapping bike seat and a shock-absorbing microcontroller enclosure.
Large language models (LLMs) are used to generate user interface (UI) code, yet the accessibility of this code is difficult to evaluate in a controlled way. Existing evaluations typically examine full-generated webpages or loosely specified tasks, which makes it difficult to determine where accessibility outcomes come from. We introduce PACE for “Prompt Accessibility Controlled Evaluation,” a benchmarking testbed for controlled evaluation of accessibility in LLM-generated HTML form components. Using PACE, we evaluated the accessibility of 58 form components generated by five developer-centric LLMs with variations across three system prompts with increasing accessibility guidance, and three request variants containing increasing detail about each form components. We collected 10 trials per configuration for a total of n = 26,100 outputs. Our findings show that accessibility in LLM-generated code moved with prompt construction and with the circumstance around it (e.g., model, form component, and measure used to assess the output). This pattern calls for evaluation designs that can better separate sources of variation in the accessibility of LLM-generated code.
Yumeng Ma, Jacob O. Wobbrock, Joe Devon, Aaron Gustafson, Michael Fairchild, Jennifer Mankoff, and Venkatesh Potluri. 2026. Prompt and Circumstance: Evaluating Accessibility in LLM-Generated HTML Form Components. In Proceedings of the 28th International ACM SIGACCESS Conference on Computers and Accessibility (ASSETS ’26). ACM. (pdf)
Aaleyah Lewis, Aayushi Dangol, Hyewon Suh, Abbie Olszewski, James Fogarty, Julie A. Kientz. In Proceedings of the 2025 CHIConference on Human Factors in Computing Systems (CHI ’25),
Speech-language pathologists (SLPs) provide support to children with speech and language difficulties through delivering evaluation, assessment, and interventions. Despite growing research on how Artificial Intelligence (AI) can support SLPs, there is limited research examining how AI can assist SLPs in delivering equitable care to culturally and linguistically diverse (CLD) children with disabilities. Through interviews with 15 SLPs and a two-part survey study with 13 SLPs, we report on SLP challenges in delivering responsive care to CLD children with disabilities (i.e., unrepresentative materials, unreliable translation, insufficient support for language variations), areas for AI-based support, evaluations of how available AI performs in addressing these challenges, and bias assessments of AI-generated materials. We discuss implications of contextually unaware AI, the range of care in AI prompting, tensions and tradeoffs of AI-based support, and honoring diverse representations in AI-generated materials. We offer considerations for SLPs using AI-based tools and general-purpose AI in their practice.
Tobias M. Weinberg, Aaleyah Lewis, Ricardo E. Gonzalez Penuela, Weicong Hong, Jennifer Mankoff, Thijs Roumen. ASSETS 2026.
Voice is a central element of identity. We recognize people by their voice, and we uniquely express who we are with it. For people who rely on augmentative and alternative communication (AAC) systems, such as speech-generating devices (SGD), the device’s voice becomes an identity marker others associate with them. Yet, it is hard to find a voice that truly aligns with one’s identity both linguistically and culturally. Although modern AI-generated voices can reproduce diverse accents and speaking styles, AAC users still lack accessible ways to articulate how they want an identity-aligned voice to sound like. We first conducted a survey of AAC users (across eight countries) to characterize current voice representation, finding that non-binary, transgender, and non-US born respondents rated their current voice support identity alignment consistently lower than other respondents. To examine how AAC users respond to voices designed to reflect their cultural identity, we built a tool that elicits cultural markers through guided questions and generates personalized voice candidates for participants to hear and reflect on. After participants heard the voices, we interviewed them to examine what it means for a voice to feel culturally representative, how they interpreted voices with cultural connotations, and how these voices shaped their sense of identity and agency. Our findings show that cultural voice alignment runs deeper than accent or language alone; it touches on belonging, self-recognition, and what it means to be heard as who you are.
Blind or low vision (BLV) students face systemic digital barriers in STEM education. Among these barriers, a significant one is inaccessible lecture slides, particularly when ALT (alternative) text for visuals is missing or inadequate. ALT text can be onerous for experts to create for visual-heavy slide decks, and non-experts may not create informative ALT text. AI-powered generation techniques have promise to speed this process up, however AI text outputs can be inaccurate. To investigate this, we constructed a dataset of 30 lecture slide PDFs across 5 STEM domains.
To generate ALT text for the lecture visuals, we developed a research-backed system prompt and internal AI-powered interface that uses lecture slide PDFs and slide-aligned transcripts. We ran an ablation study comparing image understanding of 795 lecture visuals under two conditions: lecture slide PDF and lecture slide PDF with additional transcript context. We scored the ALT text items across research-informed metrics such as Accuracy, Objectivity, Completeness, and Relevance. The AI-generated ALT text scored highly overall across all metrics in both research conditions, with minimal rates of hallucination. Both conditions performed equally well in most cases. For Illustrations, Completeness was +21.2% higher (𝑝 < .001) with transcript context.
Overall, our findings demonstrate the technical feasibility of AI-powered ALT text generation for STEM lecture visuals using multimodal context. These results motivate and lay the groundwork for future BLV student user evaluations to further analyze how AI systems can support educational accessibility
A. Turkarslan, V. H. Thakkar, R. Tekle, T. Chen, J. J. Martinez, and J. Mankoff. “Context-aware, AI-powered ALT text generation for lecture visuals: a multimodal approach via slide decks and speech transcripts”. Proceedings of the 28th International ACM SIGACCESS Conference on Computers and Accessibility, ASSETS 2026. ACM, 2026. (pdf).
Full System Prompt Used
You are an accessibility assistant that generates high-quality alternative text (ALT text) for lecture slide visuals.
For each slide, detect meaningful visuals and generate ALT text for each one. If transcript context is provided, use it only to clarify visible content. If transcript context conflicts with the slide, trust the slide.
Return JSON only (no markdown, no extra text).
Schema: {
  "slides": [
    {
      "slideNumber": number,
      "visuals": [
       {
        "id": string
        // (in the form of slide#-visual#"),
        "type": string
        // (such as "diagram", bar chart", line
        // graph", "scatter plot", "illustration",
        // "photograph", "infographic", "flowchart",
        // etc.)
        "altText": string
       }
      ]
    }
  ]
}
Rules:
slideNumber starts at 1 and increments by 1.
If a slide has no visuals, return “visuals”: [].
One visual object per distinct visual. A distinct visual is a self-contained diagram, chart, image, or composite graphic that conveys a unified concept or message.
If multiple visual elements on a slide are clearly connected or part of a single diagram, chart, or composite visual, treat them as ONE visual and describe all parts together in a single altText.
altText must be accurate, relevant, complete, specific, and focused on instructional meaning (i.e. key elements, labels, relationships, directional indicators, and trends).
altText should be within a range of 2-8 sentences as needed.
When arrows, lines, or labels are present, explicitly describe what each one points to, where it is positioned relative to elements, and what relationship or flow it indicates (i.e. direction, sequence, or connection).
If the visual is a data visualization or informational graphic (ex. chart, graph), begin altText by stating the chart type and a brief summary of what it shows. Describe the axes and structural components, key data trends and relationships, and reference data labels or categories, highlighting any important comparisons or patterns that support understanding.
You may weave brief relevant semantic context from prior slides and/or transcript into the literal visual description when it improves clarity.
If transcript is present, use it when it improves precision or semantic meaning of visible elements (i.e. disambiguating acronyms, variable meaning, chart intent, or why a visual step matters).
Keep context tightly anchored to visible elements; do not add standalone context that is not grounded in what is on screen.
If a similar or repeated visual appears across multiple slides (even if slightly modified), treat each instance as independent. The altText must fully describe the visual as it appears on the current slide without assuming prior context or that the user has seen earlier slides. You may briefly note that the visual builds on or repeats a prior slide if helpful, but the description must remain fully understandable on its own.
Avoid filler/openers like “This image shows” or “This slide shows”.
Write altText as direct description only (no bullets, no labels like “ALT text:”, no markdown
Do not generate ALT text for a small video or image of the instructor unless it conveys instructional meaning (i.e. demonstrating an action, pointing to content, or containing relevant visual information). Otherwise, treat it as decorative.
If purely decorative, set altText to “”
If a value or label is not clearly visible, do not guess it.
If uncertain, describe only the clearly visible high-confidence elements.
Shuxu “Sev” Huffman (they/them) is a PhD student at Gallaudet University and Université Paris-Saclay, where they are affiliated with the Laboratoire Interdisciplinaire des Sciences du Numérique (LISN). They are advised by Dr. Raja Kushalnagar at Gallaudet University and Dr. Patrick Bourdot and Dr. Tifanie Bouchara at Université Paris-Saclay. They earned both their bachelor’s and master’s degrees from the University of Washington and have maintained a long-term research collaboration with the Make4all Lab and Dr. Jennifer Mankoff.
Sev studies Deaf technology and the role technology can play in Deaf people’s lives. Their work examines how technologies can be designed and positioned to support Deaf people without treating technology simply as a way to remediate hearing loss or communication difference. Their research spans areas including sign language AI, sport technologies for disabled athletes, and immersive learning environments, with a broader interest in how technology can fit into Deaf ways of communicating, learning, interacting, and moving through the world.
Ella Williams (she/her) is a PhD student in the Paul G. Allen School of Computer Science and Engineering at the University of Washington. She is advised by Dr. Jennifer Mankoff. She completed her undergraduate studies at Macalester College in St. Paul, MN, where she double-majored in Computer Science and Geography, with a minor in Critical Theory.
Ella’s research interests lie in accessible making, with an emphasis on making computer-aided design (CAD) accessible to enable all to pursue a higher-education in engineering.
Gyeongdeok Kim is a Ph.D. candidate at the Gwangju Institute of Science and Technology (GIST) in South Korea, advised by Professor Gunhyuk Park. He is currently visiting the Make4All group at the University of Washington, working with Professor Jennifer Mankoff. His research interests include human-computer interaction, accessibility, and haptics, with a focus on assistive technologies for blind and low-vision people.
His work includes I-Scratch, a system for creating presentation slides through tactile and auditory interaction with AI assistance, and I-VAMOS, a system for independent and private voting with paper ballots. He is currently studying the training practices and experiences of goalball players and coaches, including individual practice, feedback, and team coordination.
Disabled people live at the intersection of multiple identities that shape their access needs and technology experiences. Designing equitable systems requires preparing future technologists to critically engage with how technologies interact with systems of oppression. We approached a quarter-long capstone course with one central question: Do the processes and expectations of engineering education (in the context of an accessibility capstone) adequately incorporate multiple intersectional perspectives? By using this as a guiding pedagogical framework, we uncovered gaps in standard processes and requirements and developed practical solutions for addressing them. We outline the theoretical foundations informing the course, its structure and implementation, and reflect on the tensions that emerged throughout the course. We offer considerations for educators seeking to meaningfully integrate intersectional accessibility into computing education.
Data structure diagrams play a central role in computer science education by supporting students’ understanding of abstract data types and the structural relationships that define their properties and behaviors. However, accessibility practices often reduce these diagrams to linear descriptions, which can obscure the relational structure necessary for computational understanding. This approach limits blind and visually impaired learners’ access to the fundamental structure of computation. Drawing on theoretical frameworks that conceptualize diagrams as structured representations, as well as on experiences in designing and evaluating accessible data structure representations, we advance a perspective that reframes accessibility for these diagrams as access to relational structure rather than solely linear, visual description. We conclude with implications for computer science education, accessibility policy, and future research on equitable access to core computational concepts.
We also built a solution that automatically creates accessible representations from structural information about diagrams. Based on a Wizard-of-Oz study, we derive design requirements for an automated system, Arboretum, that compiles text-based diagram specifications into three synchronized nonvisual formats—tabular, navigable, and tactile. Our evaluation with BVI users highlights the strength of tactile graphics for com- plex tasks such as binary search; the benefits of offering multiple, complementary nonvisual representations; and limitations of exist- ing digital navigation patterns for structural reasoning. This work reframes access to data structures by preserving their structural properties. The solution is a practical system to advance accessible CS education.
Wimer, B.*, Kanchi, R.*, Frierson, K., Potluri, V., Metoyer, R., Mankoff, J., Natsuhara, M., & Wang, M. (2026). Nonvisual Support for Understanding and Reasoning about Data Structures. In Proceedings of the 2026 CHI Conference on Human Factors in Computing Systems (CHI ’26), April 13–17 (html)
Brianna L. Wimer, Ritesh Kanchi, Jennifer Mankoff, Ronald A. Metoyer: Diagrams Are Structures: Reframing Accessibility for Data Structure Diagrams. RESPECT 2026: 1-6 (html)